CardDefender: Fraud Detection
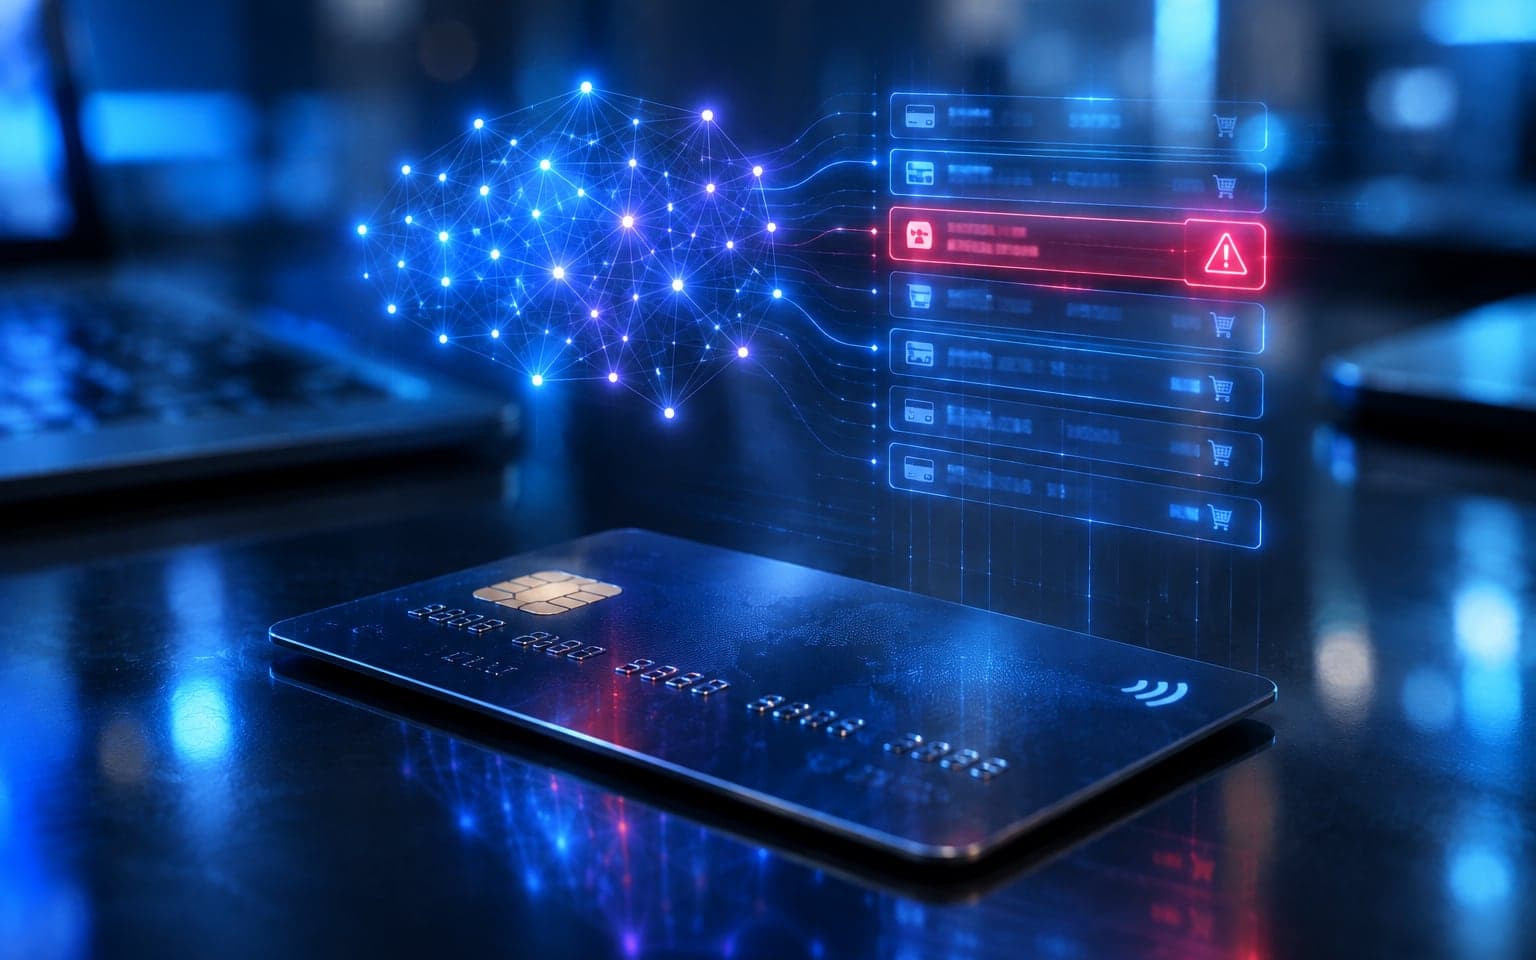
A fraud pipeline built for an extremely imbalanced transaction dataset.
Handles the class imbalance that makes fraud detection hard: resampling, threshold tuning and models chosen for recall on the fraud class rather than raw accuracy, with a full evaluation of precision, recall and F1.
README · rendered from GitHub
CardDefender: Credit Card Fraud Detection Pipeline


1. Problem Statement
Credit card fraud is a major financial challenge. Millions of transactions occur daily, and fraudulent activity can cause significant monetary loss. Manual inspection of transactions is impossible due to data scale and speed requirements.
Goal: Build a machine learning pipeline that identifies fraudulent transactions accurately, even when the dataset is extremely imbalanced.
2. Motivation
- Fraudulent activities cause billions in financial loss annually.
- Transaction data streams are high volume and must be processed automatically.
- Fraud cases are rare, which makes traditional machine learning techniques perform poorly.
- Building a reliable fraud detection system is crucial for banks, fintech services, and e-commerce.
Why this project matters: A strong fraud detection model improves financial security, protects customers, and enhances trust in digital payment systems.
3. Dataset Description
- Total Rows: 284,807 transactions
- Fraudulent Transactions: 492
- Legitimate Transactions: 284,315
- Fraud Ratio: 0.172 percent
Features:
-
Most features (
V1toV28) are PCA-transformed to protect customer privacy. -
Includes
AmountandTimefeatures. -
Classcolumn is the target:- 0 = Legitimate
- 1 = Fraudulent
Dataset Used: Kaggle – Credit Card Fraud Detection Link: https://www.kaggle.com/datasets/mlg-ulb/creditcardfraud
This dataset contains real credit card transactions made in Europe. It is highly imbalanced, with fraudulent transactions making up only 0.172 percent of the data.
4. Challenges
-
Severe Class Imbalance Fraud cases are extremely rare, making it difficult for classifiers to learn meaningful patterns.
-
Hidden Patterns Features are PCA components, so fraud patterns are not directly interpretable.
-
High Precision Required False positives inconvenience customers, while false negatives allow fraud to pass undetected.
5. Project Pipeline
- Load and explore dataset
- Handle imbalance (SMOTE, undersampling, oversampling or class weighting)
- Preprocess features (scaling, splitting)
- Train models (Random Forest, Logistic Regression or others)
- Evaluate using metrics suitable for imbalanced data
- Compare performance for balanced vs. imbalanced approaches
- Generate confusion matrix and classification report
- Final conclusions and improvements
6. Handling Imbalanced Data
Your notebooks include two approaches:
A. Without Balancing
- Train ML model directly on the original dataset
- Model tends to predict everything as non-fraud
- High accuracy, low recall
B. With Imbalance Handling (SMOTE / Undersampling / Oversampling)
- Balances the dataset before training
- Helps model detect minority (fraud) cases
- Improves recall and F1-score for fraud class
7. Models Used
The notebooks generally include:
Random Forest Classifier
- Handles nonlinear patterns
- Robust and easy to tune
- Works well on fraud datasets
Logistic Regression (optional)
- Baseline linear model
- Useful for comparison
8. Evaluation Metrics
9. Confusion Matrix Interpretation
A confusion matrix helps analyze:
- True Negatives (legitimate correctly identified)
- True Positives (frauds correctly caught)
- False Negatives (frauds missed — most dangerous)
- False Positives (legitimate flagged as fraud — customer inconvenience)
Balancing techniques usually reduce False Negatives, which is essential for fraud systems.
10. Insights & Discussion
- Imbalance handling dramatically improves fraud detection.
- Random Forest generally performs better than Logistic Regression in nonlinear PCA-transformed space.
- Fraud patterns exist but require proper feature scaling and minority oversampling to be learned.
11. Limitations
- PCA transformation hides interpretability
- Synthetic balancing (like SMOTE) may introduce noise
- Dataset lacks real-world contextual features such as location, merchant ID, or device type
- Models may not generalize perfectly to new fraud strategies
12. Future Work
- Use XGBoost or LightGBM for improved detection
- Add time-series modeling (fraud often shows patterns over time)
- Implement anomaly detection methods
- Deploy model in real-time detection pipeline
- Train transformer models for sequential fraud detection
13. Glossary
- SMOTE: Synthetic Minority Oversampling Technique
- Oversampling: Duplicate or synthesize more minority samples
- Undersampling: Remove majority samples
- PCA: Dimensionality reduction technique used for anonymization
- Precision: Correct fraud predictions
- Recall: Ability to detect fraud cases
- F1 Score: Balanced metric for imbalanced datasets
More in AI / ML
Related projects
 Private repoAI / MLSummer 2026
Trans-Neptunian Object Detection
A spatiotemporal U-Net that finds faint moving objects in telescope image sequences.
- PyTorch
- Python
- HDF5
- CANFAR
 AI / ML2023
SkinSense: Skin Cancer Classifier
An ensemble of five models labels a lesion as benign or malignant from one RGB image.
- Python
- Scikit-learn
- XGBoost
- LightGBM
 AI / ML2025
RecycleVision
EfficientNetB0 transfer learning sorts waste into six recyclable categories.
- Python
- TensorFlow
- Keras
- EfficientNetB0