ShroomSafe
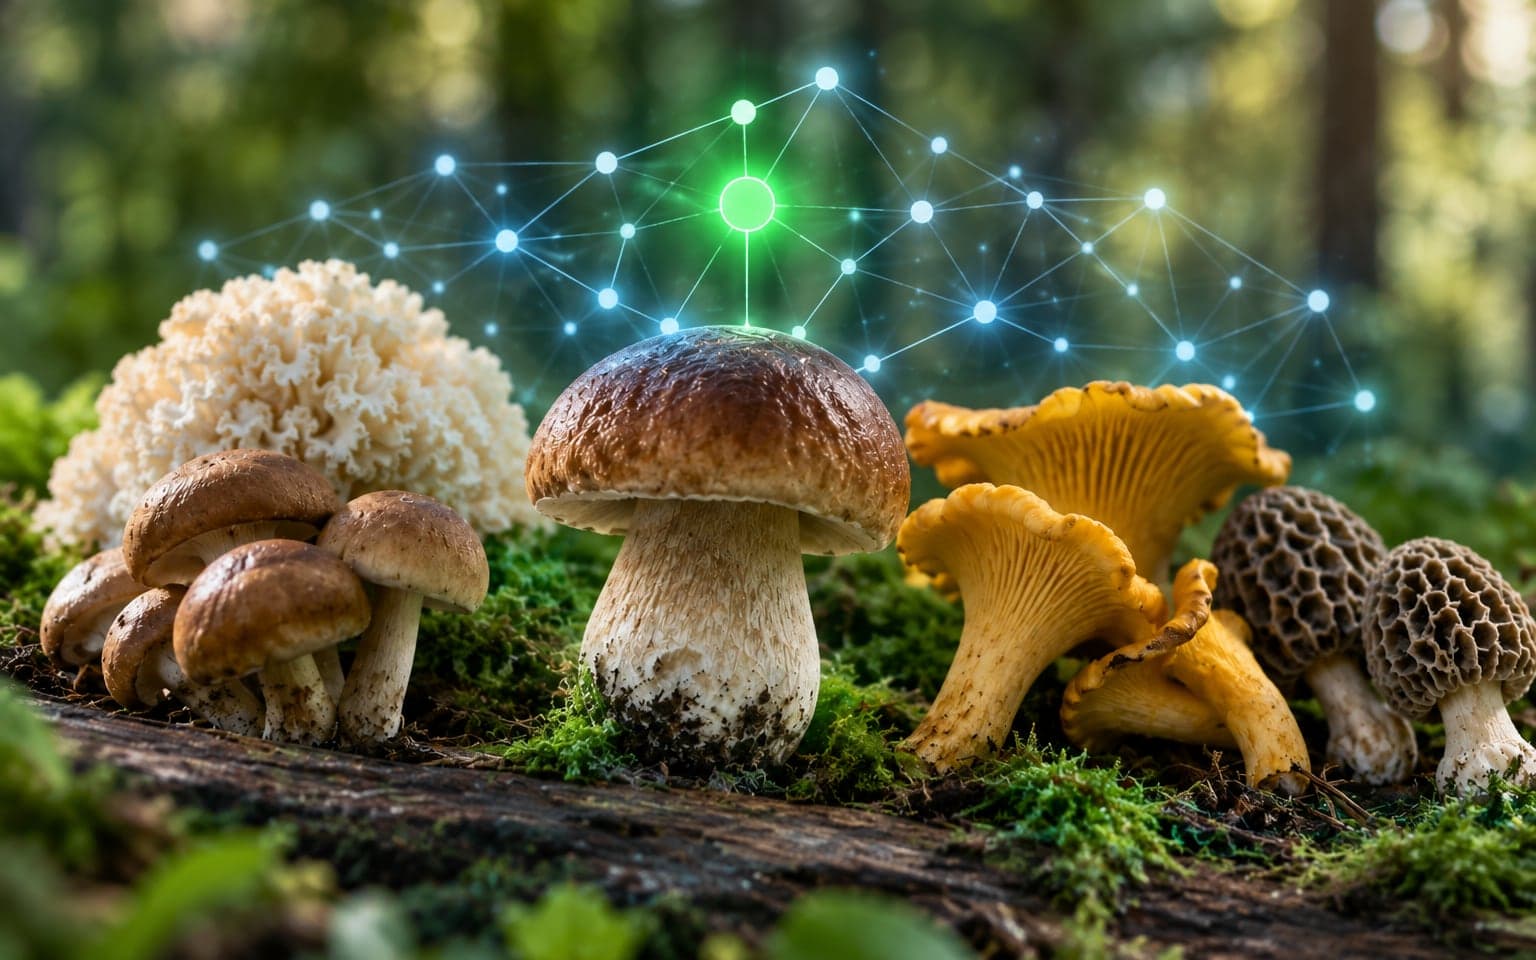
Decision trees and random forests decide whether a mushroom is edible or poisonous.
A binary classifier on physical mushroom features where the cost of a false negative is severe. The project compares a single decision tree against a random forest and reports accuracy, F1 and confusion matrices with a focus on precision for the edible class.
README · rendered from GitHub
ShroomSafe: Predicting Mushroom Toxicity



1. Title
ShroomSafe: Predicting Mushroom Toxicity Decision Tree and Random Forest based classification of edible and poisonous mushrooms.
2. Problem Statement
Wild mushrooms can be edible or poisonous. Many of them look very similar. For a normal person it is hard to tell which mushroom is safe and which is dangerous. The task is Given the physical features of a mushroom, predict if it is edible or poisonous. This is solved as a binary classification problem using Decision Tree and Random Forest models.
3. Motivation
- Mushroom poisoning can cause serious illness or even death.
- Visual inspection alone is risky because some edible and poisonous species look alike.
- The mushroom dataset is a classic example for learning classification, decision trees and feature importance.
- Decision Tree and Random Forest models are easy to interpret and work well with categorical features.
This project is mainly for learning and demonstration, not for real life medical use.
4. Dataset
Source UCI Machine Learning Repository Mushroom Classification Dataset (you can also mention the Kaggle mirror if you used it)
Size and classes
-
Total samples: 8124 mushrooms
-
Two target classes
- 0 or e: edible
- 1 or p: poisonous
Features
All features are categorical. Some important ones:
- cap shape
- cap surface
- cap color
- bruises
- odor
- gill attachment, spacing, size, color
- stalk shape, root, surface above and below ring
- ring number and type
- spore print color
- population
- habitat
No missing values are present.
5. System Pipeline
You can draw this as a simple block diagram.
- Load mushroom dataset
- Explore distributions with bar charts
- Encode categorical features to numeric labels
- Split into train and test sets
- Train Decision Tree and Random Forest models
- Evaluate models using accuracy, F1 score and confusion matrix
- Choose Random Forest as final model
- Use model to predict toxicity for new mushroom samples
6. Exploratory Data Analysis
You plotted many bar charts to understand the distribution of each feature.
6.1 Class distribution
- Edible and poisonous classes are almost perfectly balanced. This means class imbalance is not a problem here.
6.2 Cap shape
Plots show that:
- Most mushrooms are convex or flat.
- Fewer mushrooms are knobbed or bell shaped.
- Very few are sunken or conical.
This helps understand which shapes are common in the dataset.
6.3 Odor
The odor distribution is very important.
- The most frequent odor is none.
- Foul odor is also very common.
- Other odors appear with smaller counts: spicy, fishy, almond, anise, pungent, creosote, musty.
From later analysis we see that odor is one of the strongest indicators of toxicity.
6.4 Other features
You also plotted the distribution for:
- cap surface and cap color
- presence of bruises
- gill attachment, spacing, size, color
- stalk shape, root, surface and color
- ring number and ring type
- spore print color
- population and habitat
These plots show that different categories of a feature have very different frequencies. This also hints that some categories are strongly linked to edible or poisonous mushrooms.
7. Data Preprocessing
Steps used in the notebook:
- Load the mushroom data into a DataFrame.
- Encode all categorical columns to integers using LabelEncoder or similar method.
- Separate features
Xand target labely. - Split the data into training and test sets, for example 80 percent train and 20 percent test.
No scaling is needed because all features are encoded categories, not continuous numbers.
8. Models
The project trains and compares two models.
8.1 Decision Tree Classifier
- Base model that learns simple if else rules from the data.
- Works very well with categorical features.
- Easy to visualize as a tree diagram.
Hyperparameters used in the notebook can be mentioned here (for example criterion, max depth, min samples split).
You also exported and visualized the decision tree, which clearly shows splits such as odor, gill size and spore print color.
8.2 Random Forest Classifier
- Ensemble of many decision trees.
- Each tree is trained on a random subset of rows and columns.
- Final prediction is done by majority voting.
- More robust and less likely to overfit than a single tree.
Random Forest is used as the final model because it achieves the best performance.
9. Random Forest Results
From the confusion matrix for Random Forest on the test set:
| Predicted Edible (0) | Predicted Poisonous (1) | |
|---|---|---|
| True Edible 0 | 847 | 0 |
| True Poisonous 1 | 0 | 778 |
Total test samples = 847 + 778 = 1625.
So:
- Test Accuracy = 100 percent
- Precision for edible class = 1.0
- Precision for poisonous class = 1.0
- Recall for both classes = 1.0
- F1 score for both classes = 1.0
This means Random Forest correctly classified every mushroom in the test set.
Note: Such perfect accuracy is possible on this dataset because the patterns are very strong, but in real world situations we still need to be careful about overfitting and dataset bias.
10. Feature Importance
Decision Tree based models can rank features by how much they reduce impurity.
Typically, the most important features in your notebook are:
- odor
- gill size
- spore print color
- possibly stalk root or similar features
These features are the main reasons why the model can clearly separate edible and poisonous mushrooms.
11. Limitations
- Dataset only covers specific mushroom species and conditions.
- All features are simple visual or physical traits; some real mushrooms require chemical or microscopic tests.
- Perfect performance on this dataset does not guarantee perfect performance in real forests.
- This project is for education, not for real life safety decisions.
12. Future Work
- Add cross validation to check stability of the model.
- Compare with other models such as Gradient Boosting or XGBoost.
- Build a small web app where a user can select mushroom features and see the prediction.
- Add SHAP or other explainability tools to show feature effects more clearly.
- Extend the project to multi class prediction between species instead of just edible vs poisonous.
13. Glossary
-
Decision Tree A tree structure where each internal node is a test on a feature, branches are outcomes, and leaves are final classes.
-
Random Forest An ensemble of many decision trees whose outputs are combined to get a stronger model.
-
Label Encoding Converting category values to integer codes.
-
Impurity Measure of how mixed the classes are in a node, often Gini index or entropy.
-
Confusion Matrix Table that compares true labels with predicted labels.
More in AI / ML
Related projects
 Private repoAI / MLSummer 2026
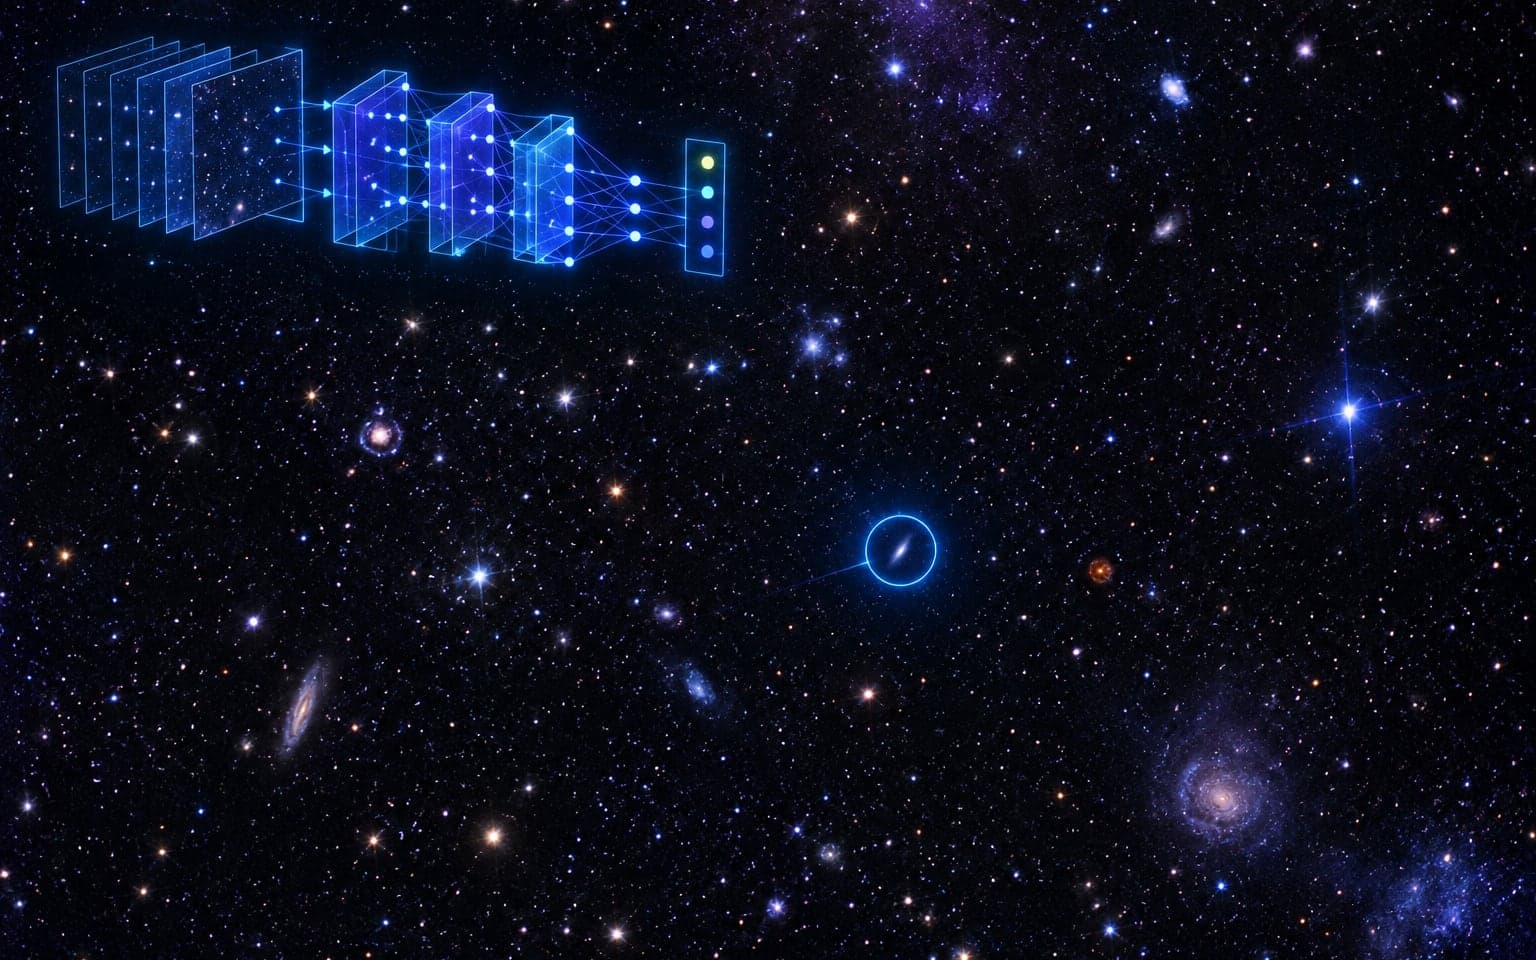
Trans-Neptunian Object Detection
A spatiotemporal U-Net that finds faint moving objects in telescope image sequences.
- PyTorch
- Python
- HDF5
- CANFAR
 AI / ML2023
SkinSense: Skin Cancer Classifier
An ensemble of five models labels a lesion as benign or malignant from one RGB image.
- Python
- Scikit-learn
- XGBoost
- LightGBM
 AI / ML2025
RecycleVision
EfficientNetB0 transfer learning sorts waste into six recyclable categories.
- Python
- TensorFlow
- Keras
- EfficientNetB0